
Understand
Build representations that connect video observations with objects, geometry, actions, and state.
SREAL AI · WORLD MODELS
We develop physically grounded video models that learn consistent dynamics—building the foundations for general-purpose world models.
OUR FOCUS
Today’s video models can generate compelling motion. Our work asks a harder question: can they learn why the world moves the way it does?
Build representations that connect video observations with objects, geometry, actions, and state.
Verify whether predicted changes are visually plausible, physically consistent, and reachable by action.
Create coherent, controllable futures across multiple agents, viewpoints, and interactive scenes.
GENERATIVE WORLD ENGINE
Our generative world engine brings video understanding, physical reasoning, scene generation, multi-agent interaction, and real-time simulation into one research-driven platform.
SELECTED RESEARCH
Open research is how we make progress legible. Explore the work, methods, demos, code, and results behind our technical direction.
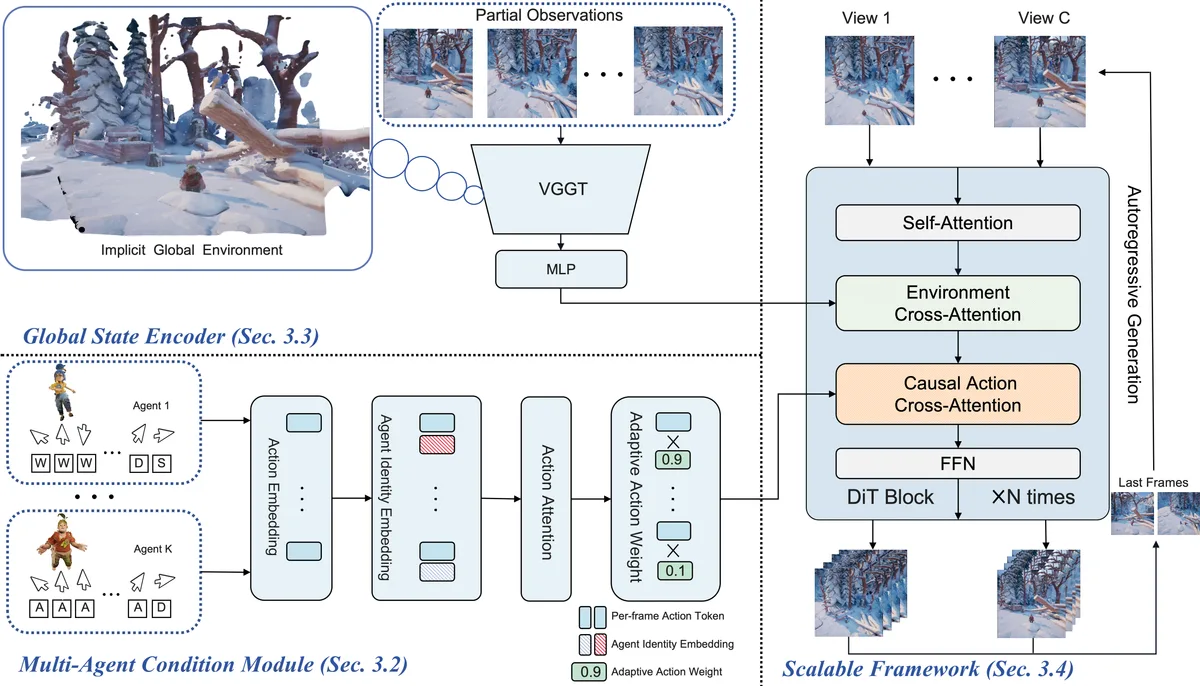
A scalable multi-agent, multi-view video world model for action-controllable and view-consistent generation.
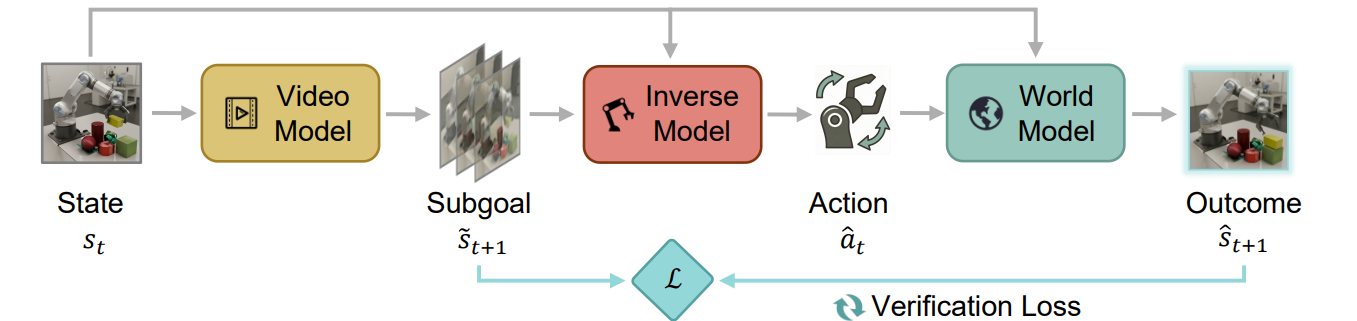
A verification framework that helps world models identify prediction errors and self-improve through forward–inverse asymmetry.
Research contributed by SREAL AI Research Intern Weifeng Lu.

FOUNDER
Founder of SREAL AI · Assistant Professor, School of Artificial Intelligence, Shanghai Jiao Tong University
Yingtian’s research explores the theory of foundational world models, self-improving systems, and consistent, interactive, efficient generative world models.
Academic profileBUILD THE NEXT WORLD MODEL
We welcome conversations with researchers, builders, game studios, and AI companies exploring physically intelligent generative systems.